
I used to work in-house at PeopleConnect where content was my bread and butter.
For anyone that hasn’t worked in “people search,” it’s a weird alternate reality of SEO. By and large people aren’t searching “background check” or “reverse phone lookup” (though they do). Instead many searches are unique first and last names + whatever personally identifiable information they have:
- Example: john smith phone number
- Example 2: jane johnson creek river lane
These sites would get millions of views and, as I’m sure you can imagine, most queries never populate in the Search Console. It makes it a weird measurement puzzle cus you can pinpoint the broad terms, but the specifics are what you optimize for and it becomes more of a feeling than a certainty. (Though considering we spend 1 hour (minimum) reporting daily, there was a pretty solid feeling of certainty.
Anyway, a big organic (by no means direct) competitor was every site dedicated to baby names. I mean, they’re huge on their own, but boy-oh-boy, when you add the UGC — they’re cascading behemoths of content!
You can imagine (or visit yourself), but take the name of ANY controversial figure in the history of the world and you’ll frequently find REAMS of paginated & threaded comments from people VEHEMENTLY arguing if the “name” should be banned or reconsidered — and it NEVER stays friendly.
Derek Digresses: As someone who hasn’t experienced 4chan, my assumption is baby name site comments are the equivalent.
Anywho, at PeopleConnect, we had access to a lot of data — A LOT.
And something I wanted to do was bite off a chunk of that baby name market with our people search sites. I wanted to leverage our data to create fun infographic for expectant parents to search and share, i.e. if you name your child Francis, here’s what percentage (in the US) graduate high school… graduate college… what most zodiac sign is… if they have a driving violation… have a criminal record… get married… get married more than once… live within 50mi of where they were born… etc etc.
I got enough buy-in that we had a working prototype — thanks in no small part to Jonah Kirangi.
However, shortly after the prototype was up, we underwent a MASSIVE merger and re-org (I almost moved from Seattle to San Diego).
I was told, the infographic concept could go live, BUT with the merger, it wasn’t clear who would be working on it, who would be maintaining it. And if the ROI couldn’t be proven, there was a solid chance this project was my proverbial rope to hang myself.
I backed off. The project didn’t go live.
And it is one of my biggest career regrets…
So I worked with Gemini to build this (above).
The US Name Dossier: How Every First Name Maps to Age, Geography, Politics, and Career
Ever wondered why almost every Chad you meet is a Gen X manager from the Midwest, why Karen over-indexes in Washington, DC and physical therapy, or why Chloe hasn’t donated to a political campaign yet?
Names are time capsules with trends rising and falling across decades, regions, and communities. Much like Nicholas Cage on SNL, your first name quietly predicts where you were likely born, your political leaning, and even the industries where people with your name are disproportionately concentrated.
Now as this is more of a “proof of concept”, above, you can look up any of the top 5,000 most common first names in US history to generate an instant demographic, political, and professional dossier. There is a plan to expand to MORE names.
Below is the exact methodology, data pipeline, and statistical guardrails behind every number.
How Each Metric Is Calculated
1. Living Population & Race/Ethnicity (2020 U.S. Census)
In April 2026, the US Census Bureau released its first decennial breakdown of first names since 1990, reporting national head counts and self-identified race and Hispanic origin across living US residents.
- Exact Living Headcount: Whenever a name appears in the 2020 Census release, the dossier displays the official Census count directly. For the handful of historical names outside the Census threshold, it falls back to an SSA actuarial survival estimate.
- Race & Hispanic Origin: Calculated directly from the Census Bureau’s six mutually exclusive categories: Non-Hispanic White, Hispanic or Latino, Non-Hispanic Black, Non-Hispanic Asian/Pacific Islander, and Other/Two or More Races (combining American Indian/Alaska Native and multiracial respondents).
2. Age Curve, Generation & Gender Split (SSA)
Using annual Social Security card applications from 1880 through 2025:
- Actuarial Survival Weighting: Because a baby born in 1925 is far less likely to be alive in 2026 than a baby born in 1995, each birth cohort is weighted by age-bracket survival probabilities to estimate the living age distribution.
- Median Age & Adult Share: Computed as the 50th percentile of estimated living bearers, benchmarked against the US national median age (39) and adult share (72.5% aged 22+).
- Generation Assignment: Mapped using standard Pew Research birth-year cutoffs based on the name’s single peak birth year (Silent/Greatest: pre-1946; Baby Boomer: 1946–1964; Gen X: 1965–1980; Millennial: 1981–1996; Gen Z: 1997–2012; Gen Alpha: 2013+).
3. Geographic Hotspot & Relative Lift (SSA State Files)
Raw birth volume always favors populous states like California, Texas, and New York. To find where a name is distinctively popular rather than just numerically large, the dossier calculates a relative concentration ratio (lift):
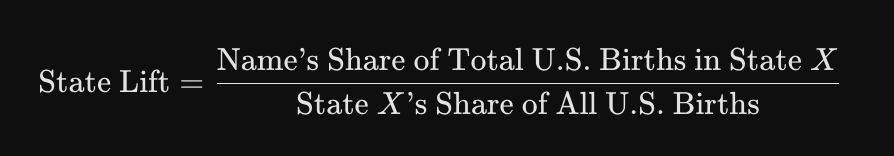
A score of 2.13x in Utah for Nathan means babies born in Utah were more than twice as likely to be named Nathan compared to the national baseline (minimum threshold of 50 state births required to prevent small-sample noise).
4. Political Donor Lean & Over-Indexed Professions (FEC)
- Unique-Person Deduplication: Because recurring small-dollar platforms (like ActBlue and WinRed) generate dozens of itemized entries per person, raw FEC records are deduplicated by
(First Name, Last Name, 5-Digit ZIP Code)so every individual is counted once rather than weighted by donation frequency. - Political Lean: Each contributor’s recipient committee is joined against the FEC Committee Master file to classify partisan alignment (
DEMvs.REP). Names with fewer than 25 unique partisan donors (such as Gen Z/Alpha names, like Chloe) are marked as insufficient sample size rather than forced into a noisy split. - Occupation Lift: Generic statuses (
Retired,Self-Employed,Not Employed,Student,Homemaker) are stripped out. Each remaining self-reported occupation is scored by dividing its share within a given first name by its share across the entire national donor pool — surfacing jobs where that name appears at least 1.15x more often than expected by chance.
Caveats & Limitations (In Plain English)
- FEC donors are older and more politically active than the general public: Itemized federal campaign contributions reflect Americans who donate to federal candidates and committees, which skews older and higher-income than the US population as a whole.
- Spellings are analyzed separately: Following SSA and Census conventions, Jon and John—or Madeline and Madeleine—are treated as distinct names, which often reveals sharp generational and regional differences between spellings.
- Top 5,000 coverage: The lookup index covers the 5,000 most frequent first names in US history, accounting for over 90% of all recorded U.S. births since 1880.
Want to Share a Dossier?
Type any name into the search bar at the top of this page and hit Copy Share Link — each name generates its own direct URL (?name=YourName) ready for Slack, group chats, or LinkedIn.